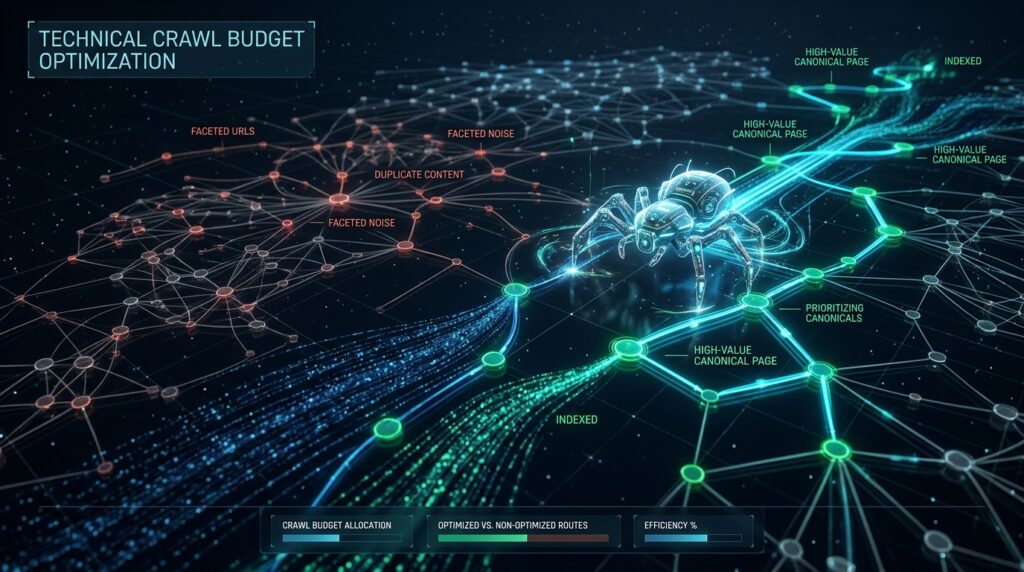
🛡️ Key Takeaways & Strategic Summary
- Understanding Crawl Budget: Googlebot allocates a limited number of requests per day based on site speed, server response stability, and content popularity.
- Eliminate Faceted Crawl Traps: Block infinite filter combinations via robots.txt and canonical tags to preserve crawl bandwidth for high-margin pages.
- Dynamic XML Sitemap Indexing: Split sitemaps into segmented batches of <10,000 URLs, prioritizing recently updated and high-converting pages.
- Server-Side Rendering (SSR) & Pre-rendering: Ensure bots receive complete semantic HTML without burning crawl budget on heavy client-side JavaScript rendering.
For enterprise e-commerce portals, real estate platforms, and directory websites containing tens of thousands of URLs, ranking on search engines is fundamentally governed by Crawl Budget and Indexing Architecture. At PixaQuant, our technical SEO and backend engineers optimize large-scale websites to ensure Googlebot crawls and indexes high-value revenue pages with maximum efficiency.
1. What Is Crawl Budget and Why Does It Matter?
Crawl Budget is the number of URLs Googlebot can and wants to crawl on your site within a given timeframe. It is determined by two main factors:
- Crawl Rate Limit: How fast your server responds. If server response times (TTFB) spike or HTTP 500 errors occur, Googlebot immediately slows down crawling to avoid overloading your infrastructure.
- Crawl Demand: How popular and fresh your pages are. High-authority pages with quality internal links are crawled frequently, while stale orphan pages are ignored.
2. Eliminating Common Crawl Budget Traps
1. Infinite Faceted Navigation & Query Parameters
E-commerce filters (e.g. ?color=blue&size=m&sort=price_asc) can generate millions of duplicate URL variations. We enforce strict robots.txt parameter disallow directives:
# robots.txt - Eliminate Faceted Filter Crawl Traps
User-agent: *
Disallow: /*?*sort=
Disallow: /*?*filter_*
Disallow: /*&sort=
Allow: /catalog/
Sitemap: https://pixaquant.com/sitemap_index.xml
2. Eliminating Soft 404s and Broken Internal Redirects
Every redirect chain (e.g. HTTP -> HTTPS -> non-slash -> slash) forces Googlebot to spend 3 crawl requests on a single destination. We audit and normalize all internal links to return direct HTTP 200 responses.
3. Segmented XML Sitemap Architecture
Large sites must never publish a single monolithic 50,000-URL sitemap. Our systems segment sitemaps logically into specialized indexes with accurate lastmod timestamps:
<?xml version="1.0" encoding="UTF-8"?>
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <sitemap>
    <loc>https://pixaquant.com/sitemap-properties-recent.xml</loc>
    <lastmod>2026-10-14T08:00:00+00:00</lastmod>
  </sitemap>
  <sitemap>
    <loc>https://pixaquant.com/sitemap-categories.xml</loc>
    <lastmod>2026-10-10T12:00:00+00:00</lastmod>
  </sitemap>
</sitemapindex>
4. Frequently Asked Questions (FAQ)
How do server response times affect crawl budget?
Faster servers allow Googlebot to crawl more pages per second without risking server overload. Reducing TTFB from 600ms to 100ms often doubles daily crawl volume.
Does `noindex` save crawl budget?
Not initially. Googlebot must still download and parse the page to discover the `noindex` tag. To truly save crawl budget on low-value pages, block crawling via `robots.txt`.
5. Scale Your Technical SEO with PixaQuant
Ensure your enterprise web portal achieves maximum organic indexation. Explore PixaQuant’s Technical SEO Services or schedule a crawl architecture audit today.
4. Log File Analysis: Monitoring Real Googlebot Behavior
Search Console reports provide only delayed aggregate statistics. To gain true real-time visibility into crawl budget efficiency, our engineers analyze raw Nginx server access logs:
- Googlebot User-Agent Verification: Perform reverse DNS lookups (
host <ip>) to verify authentic Googlebot IPs and filter out malicious scrapers spoofing crawler headers. - Crawl Distribution Audits: Track the ratio of crawl requests hitting revenue-generating product/service pages versus low-value utility pages.
- HTTP Status Code Distribution: Ensure over 95% of Googlebot requests return clean HTTP 200 responses, immediately flagging spikes in 500 errors or 301 redirect loops.
5. Internal PageRank Distribution & Link Siloing
Beyond blocking low-value filter combinations, maximizing crawl budget requires architecting strategic internal PageRank distribution:
- Hub-and-Spoke Content Silos: Category hub pages link down to subcategories and related products, with breadcrumbs reinforcing parent-child taxonomic hierarchies.
- Eliminating Orphan Pages: Every valid, indexable URL must have at least 3 internal in-content contextual links pointing to it from related high-authority articles.
- HTML Pagination Best Practices: Utilize clean
<a href="/page/2" rel="next">pagination links rather than infinite scroll JavaScript triggers that search engine spiders cannot execute.